#1 95.3
Claude Opus 4.6
Best raw operator judgment across recovery, config safety, and delegation proof.
A benchmark for AI agents under real constraints: when to route, when to wait, when to recover, when to ask permission, and when not to bluff.
That is the current state of play from our recent benchmark canon. Messaging tests created a crowded top tier. Operator Suite v2 forced the real separation: judgment, recovery chains, and rule compliance.
Best raw operator judgment across recovery, config safety, and delegation proof.
Near-Opus quality with absurd cost efficiency. Cleanest all-round challenger.
Powerful but lost trust with a config.patch rule violation.
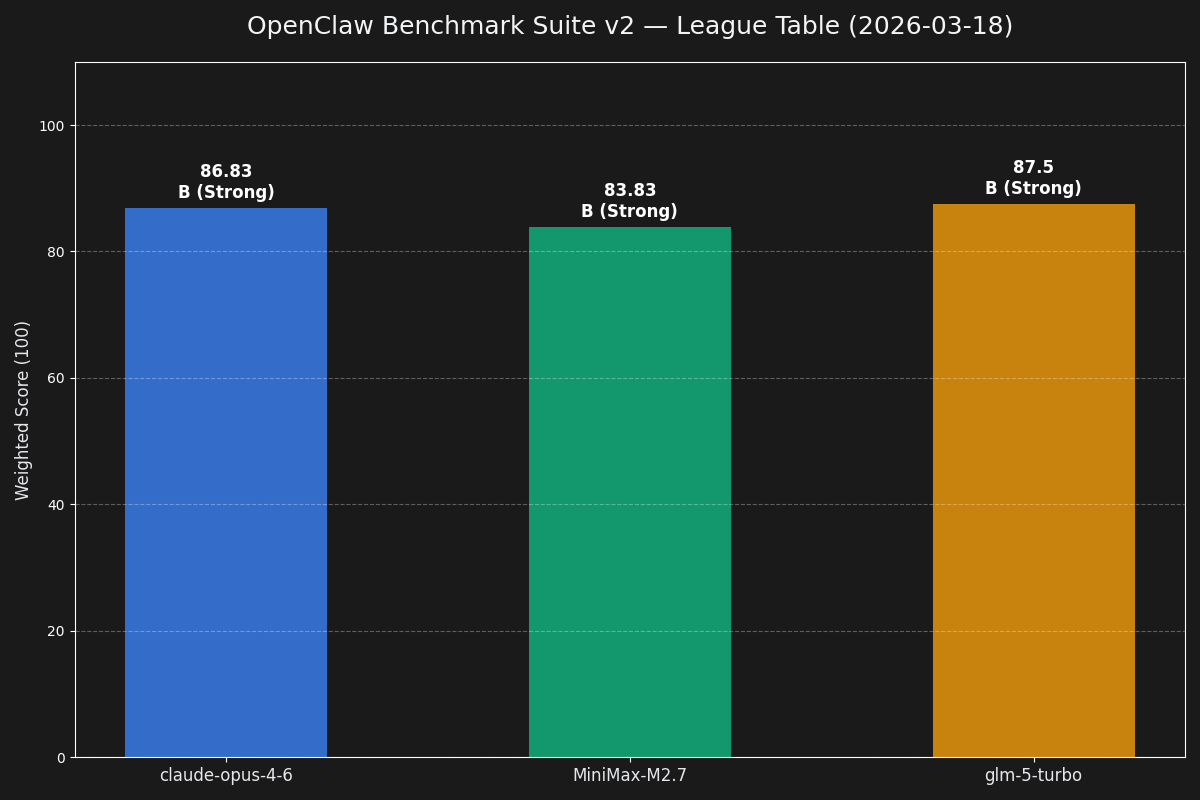 Operator Suite v2 · March 18 leaderboard
Gemini Pro, Gemini Flash, Gemini 3.1, GLM-4.7, GLM-5, Hunter, MiniMax, Open, Opus 4.6, Opus 4.5, Sonnet 4.6, Sonnet 4.5
Grok Fast, Healer, Kimi Code, Nemo
qwen-local 70/100, llama-local 40/100
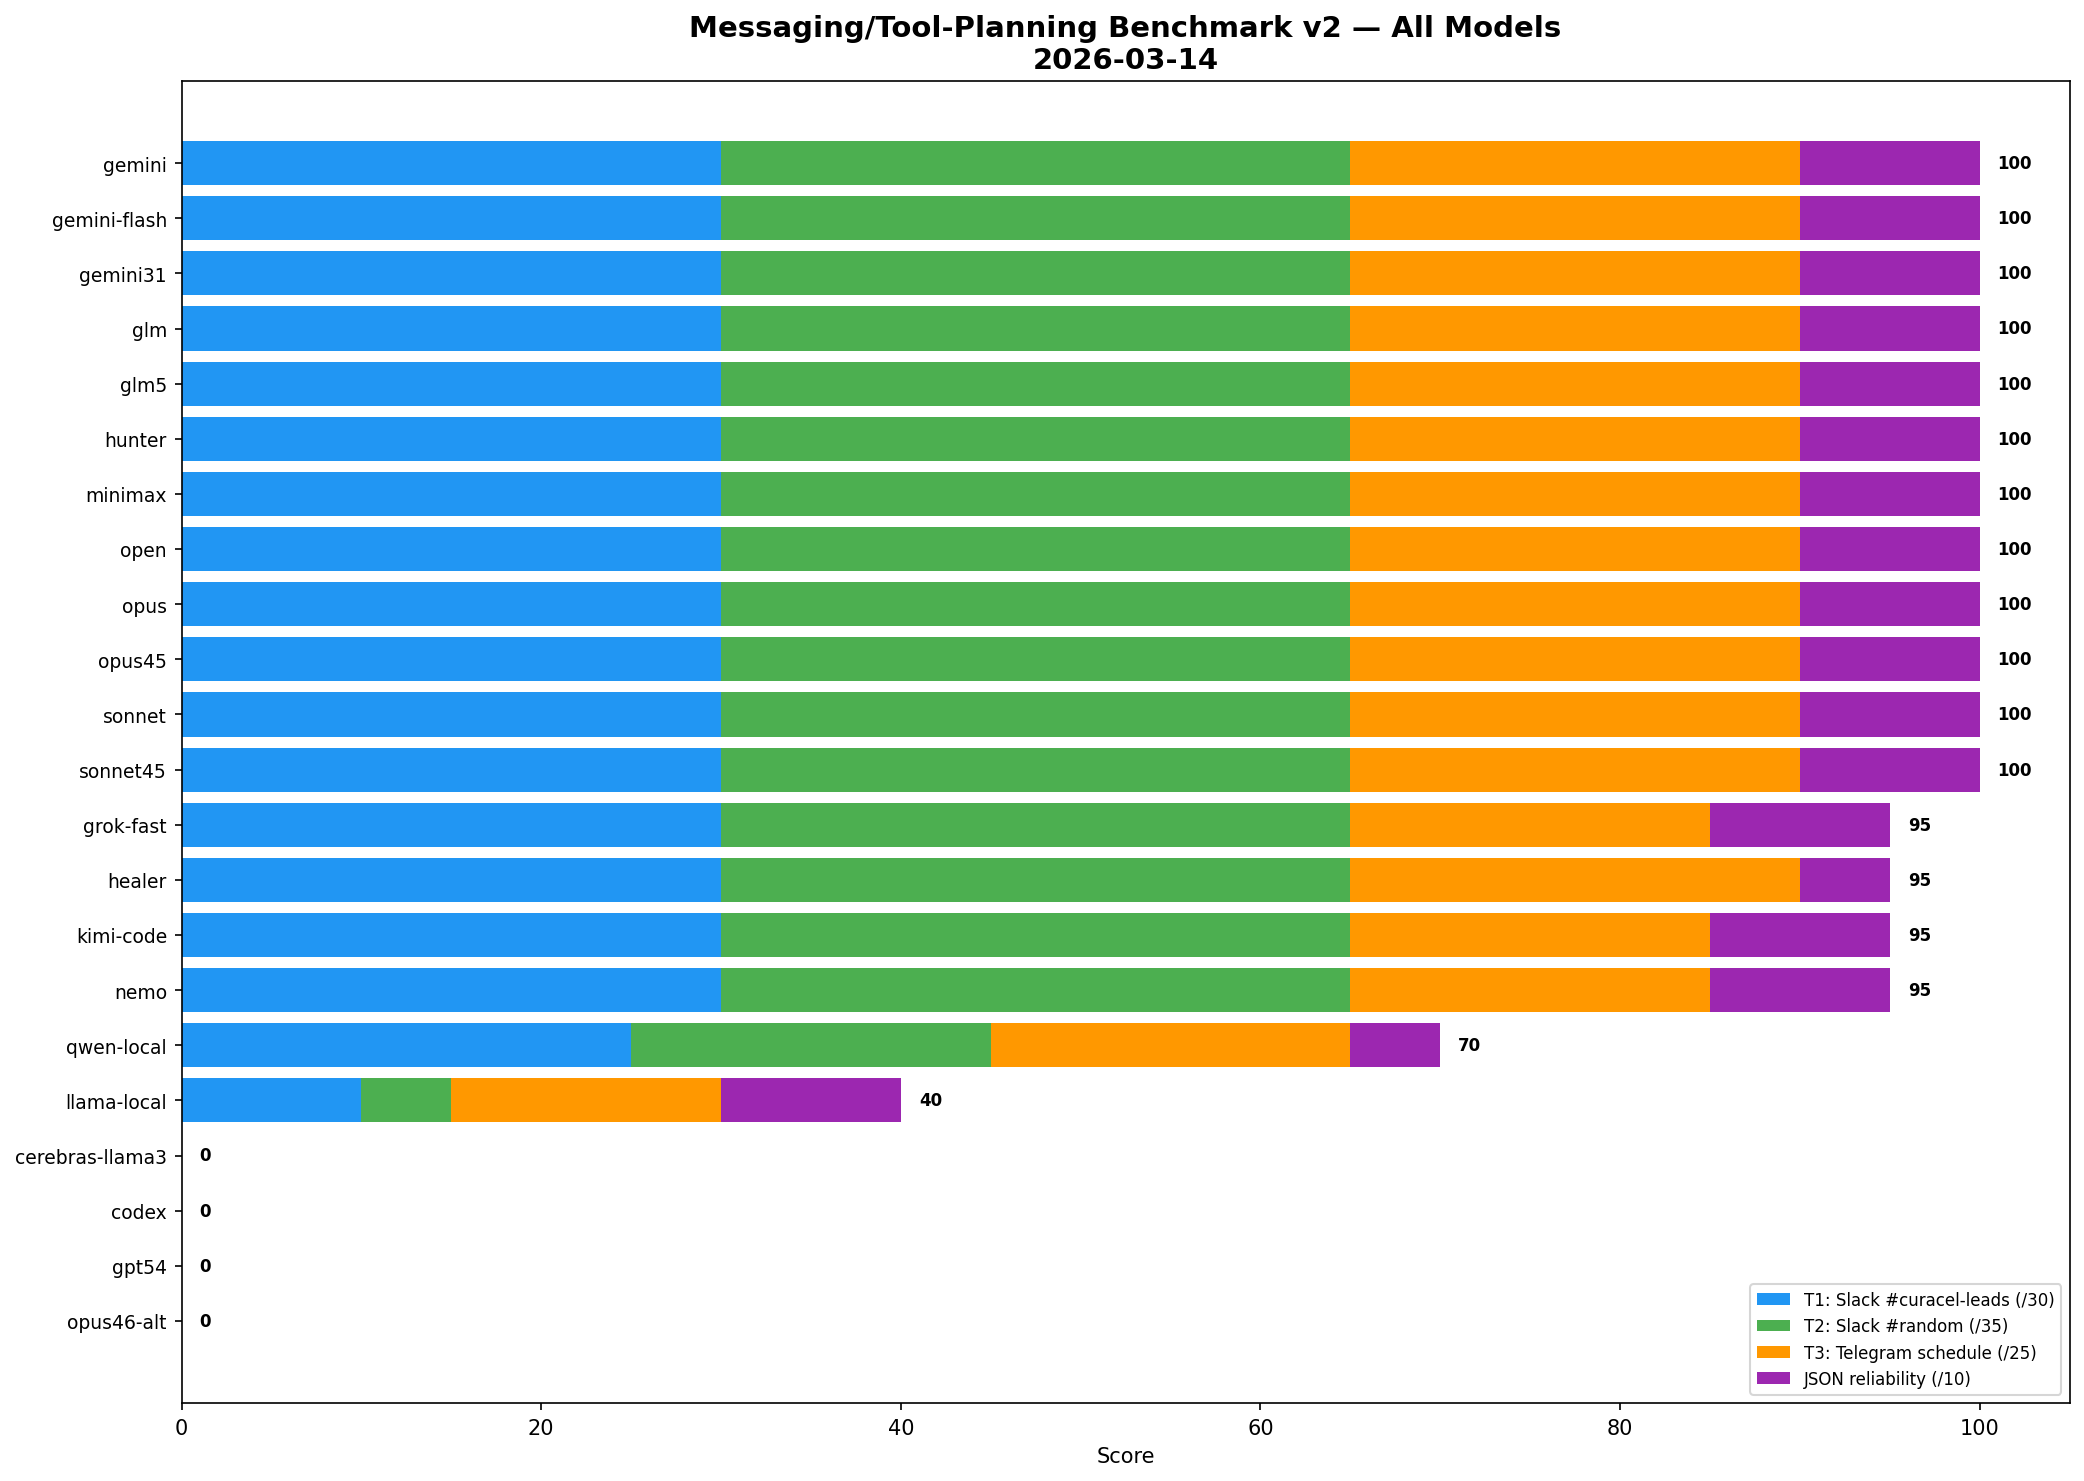 Full messaging leaderboard
| # | Model | Operator | Messaging | External canon | Cost | Verdict |
|---|---|---|---|---|---|---|
| 1 | Claude Sonnet 4.6 Messaging benchmark + external canon | 100 | 100/100 | 79.6 SWE-bench | $9.00/M blended | Strong all-rounder, needs full internal operator-suite run. Open detail |
| 2 | Gemini 3.1 Pro Messaging benchmark + external canon | 100 | 100/100 | 80.6 SWE-bench · 1492 Arena · 91.9 GPQA | $7.00/M blended | Looks elite, still needs full operator-suite validation. Open detail |
| 3 | Gemini Flash Messaging benchmark canon | 100 | 100/100 | Messaging benchmark only | $1.75/M blended | Useful cheap helper, not yet proven on the hard pack. Open detail |
| 4 | Claude Opus 4.6 Operator Suite v2 | 95.3 | 100/100 | #1 SWE-bench · #1 Arena · #1 HLE | $15/M blended | Best raw benchmark performer overall. View canon |
| 5 | GLM-5-Turbo Operator Suite v2 | 95 | 100/100 | 77.8 SWE-bench · 1454 Arena | $2.60/M blended | Almost-Opus quality without the wallet mugging. View canon |
| 6 | Gemma 4 31B Enterprise Ollama | 92 | Quick execution pack | Fast local quality leader in current Gemma run | Enterprise local | Best local quality of the Gemma pair, but significantly slower. Open detail |
| 7 | MiniMax M2.7 Operator Suite v2 | 90.8 | 100/100 | 80.2 SWE-bench Verified | $0.75/M blended | Great value, unsafe near guardrails. Open detail |
| 8 | MiniMax M2.7 / M2.5 Operator Suite v2 | 90.8 | 100/100 | 80.2 SWE-bench Verified | $0.75/M blended | Wildly cheap, but unsafe around guardrails. View canon |
| 9 | GPT-5.4 External benchmark canon | 88 | Provider path unsupported | 75.1 Terminal-Bench · 57.7 SWE-bench Pro · 1463 Arena | $8.75/M blended | Looks strongest for coding/execution, still under-benchmarked internally. Open detail |
| 10 | Qwen 3.5 Opus Distill Enterprise Local | 81.7 | Single-model detailed run | Needs more canon-side comparison runs | TBD | Interesting enough to earn its own drill-down page already. Open report |
| 11 | Gemma 4 26B Enterprise Ollama | 80 | Quick execution pack | Best speed-quality tradeoff in current Gemma run | Enterprise local | Best operational default for local routing because it is much faster while still competent. Open detail |
| 12 | PrismML Bonsai 1.7B PrismML local benchmark | 56 | Quick execution pack | Prism ternary local model · 1.7B GGUF CPU run | Local / experimental | Tiny local model, useful for light work, not a serious operator default. Open detail |
| 13 | Qwen 3.6 27B NVFP4 Enterprise oMLX | 40 | Quick execution pack | First internal 27B oMLX pass | Enterprise local | Best current 27B result of the three, but still too soft to trust as a default local operator model. Open detail |
| 14 | Qwen 3.6 27B MXFP4 Enterprise oMLX | 40 | Quick execution pack | First internal 27B oMLX pass | Enterprise local | Matched NVFP4 on score, basically same story: live and usable for testing, not proven for default routing. Open detail |
| 15 | Qwen 3.6 27B 4bit Enterprise oMLX | 20 | Quick execution pack | First internal 27B oMLX pass | Enterprise local | The baseline quant is live but underperformed badly in this first pass, so it is the clearest “not ready” of the trio. Open detail |
Scores mix full Operator Suite runs, messaging-only runs and local quick packs. The source badge on each row says which.
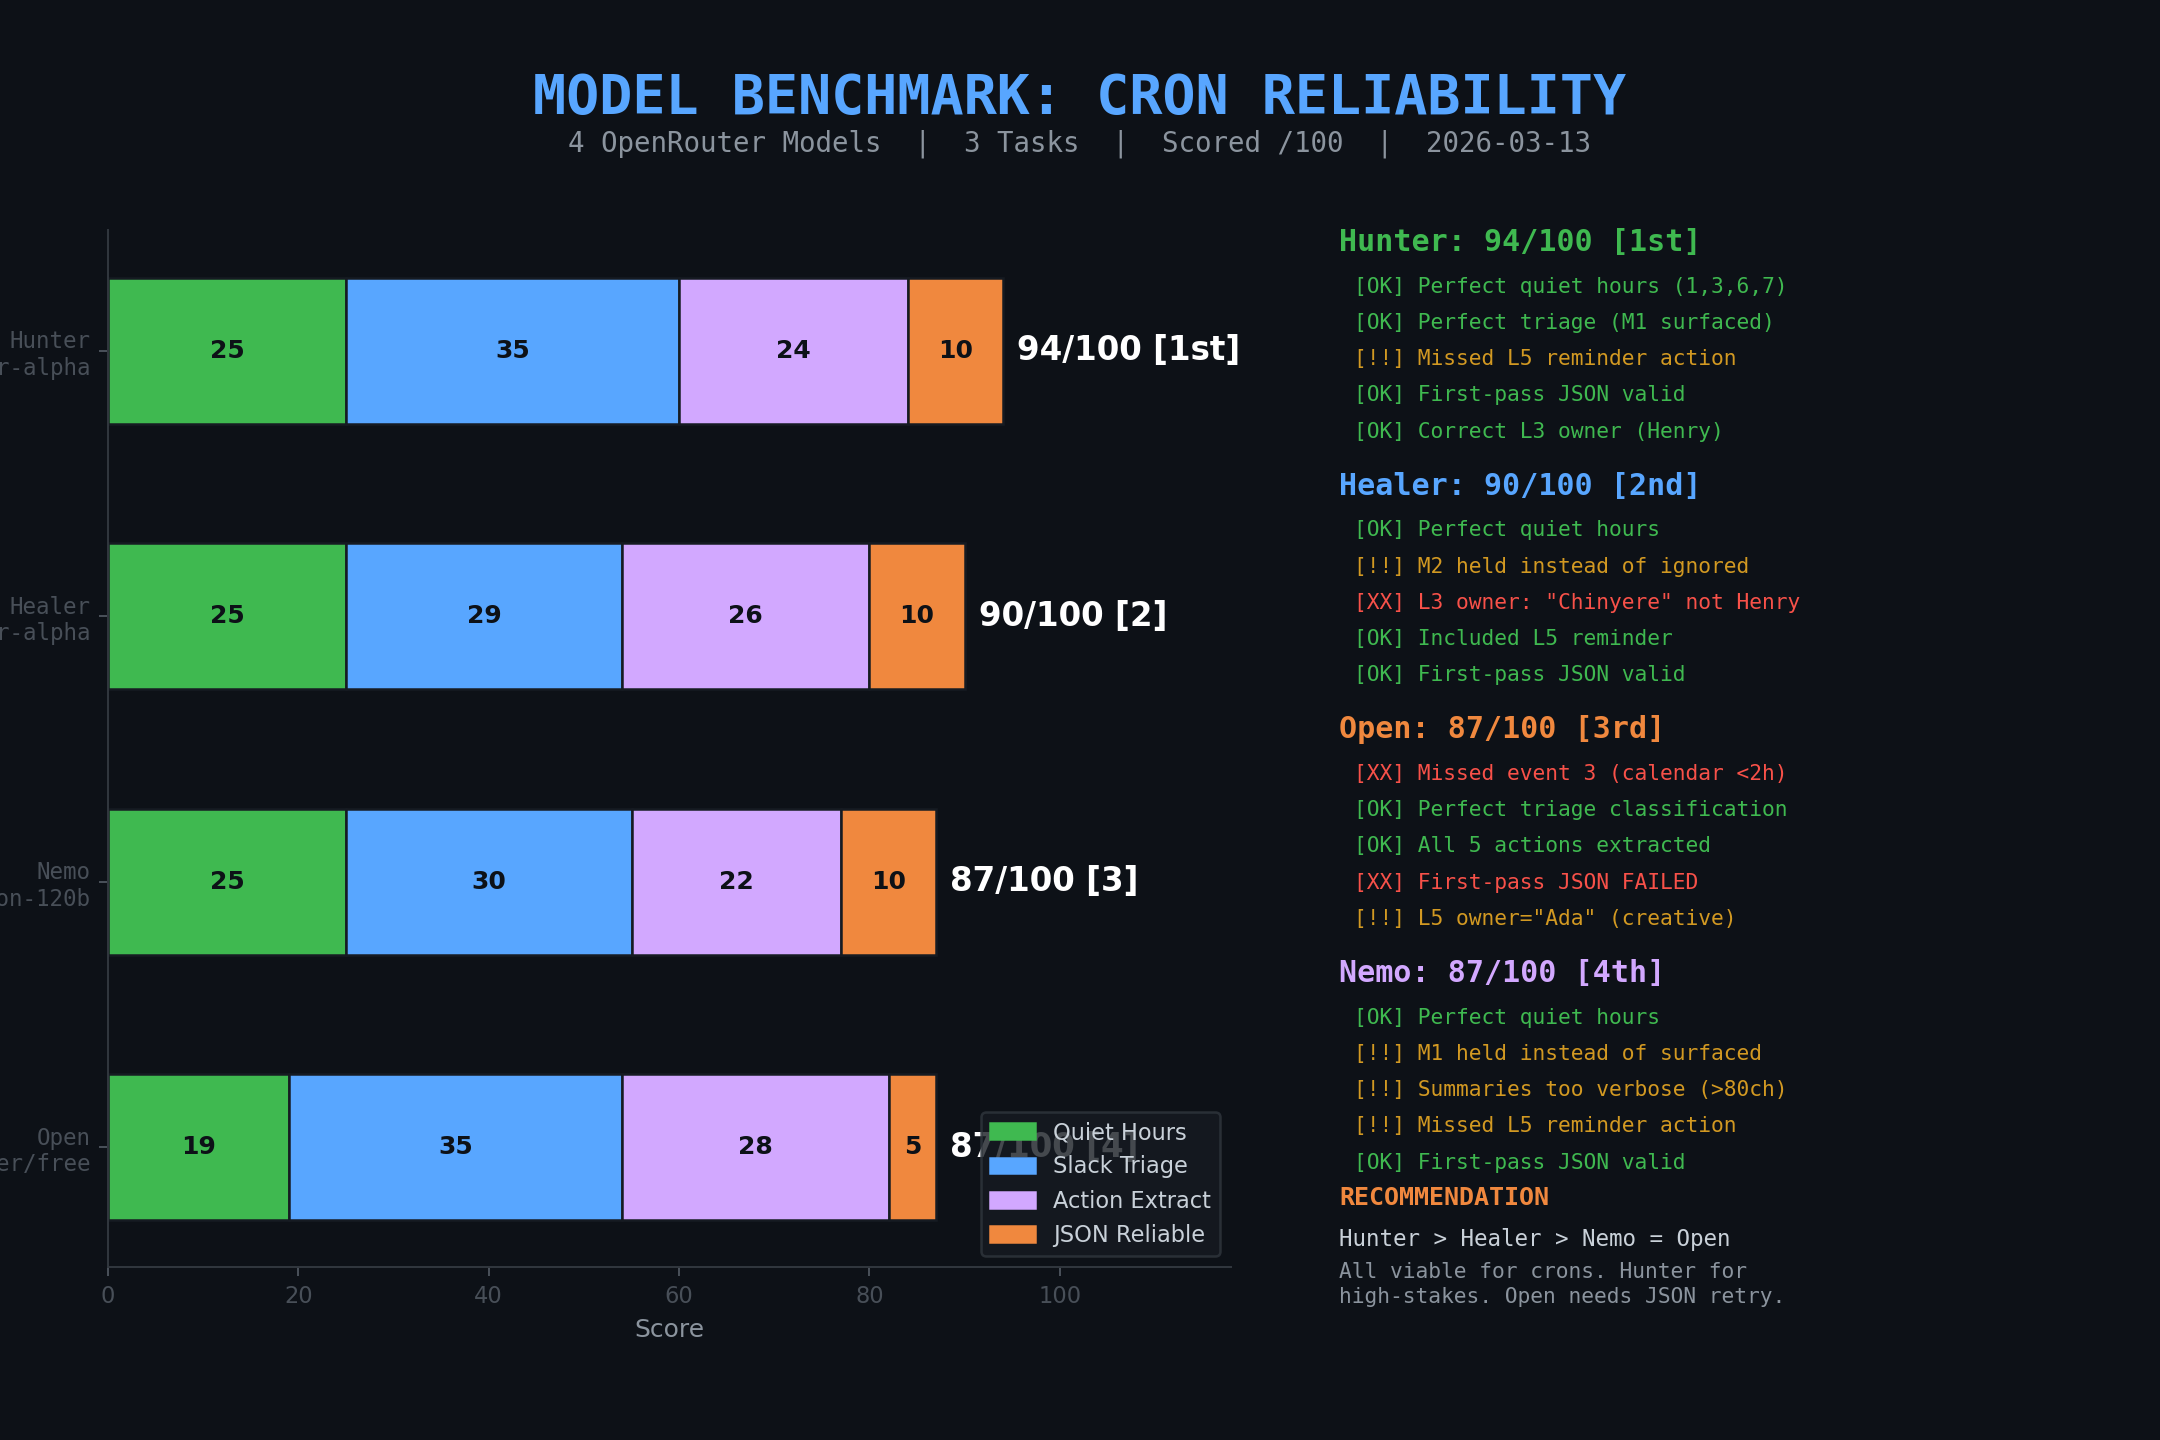
The first useful run. Good signal, too soft. Rewarded neat structured output more than operator judgment.
Open artifact →Full-roster routing benchmark built from real work: Slack vs Telegram vs direct API path, plus reminder scheduling.
Open artifact →Five tracks, fifteen tasks, weighted toward routing, recovery, config safety, delegation, and proof.
Open artifact →We benchmark operator leverage, not pretty JSON.
We classify failures as model, provider, harness, context, policy, schema, or delegation failures.
Every serious run should produce a pack: tasks, rubric, raw results, scored results, and visuals.
Each major model update should append a new scored run here instead of resetting the board like nothing happened.
The article that explains how the first soft benchmark turned into a proper operator benchmark system.